1. Introduction
A PyTorch training loop can spend most of its time waiting for data, launching kernels, or draining a CUDA queue. A model-level view alone does not tell us which side is responsible. Nsight Systems records host threads, CUDA API calls, GPU kernels, memory operations, and user-defined NVTX ranges on one timeline, letting us see when work happened and how the CPU and GPU overlapped.
We will annotate and capture a ResNet-50 training loop, read its summary tables, and use a timeline to distinguish host ranges, device operations, and synchronization waits. The code excerpts show the profiling workflow; the included tables and figures provide the worked example. A short comparison of input-pipeline settings then shows how capture length and overlap affect our interpretation, rather than aiming to find an optimal configuration.
The example uses three warm-up steps followed by eight profiled steps, batch size 128, Food-101, and an NVIDIA B300 SXM6 AC.
2. How Nsight Systems collects data
2.1 Host ranges and device execution are different intervals
The Python thread can issue a CUDA launch and continue running while the GPU executes older work. A host range such as forward measures elapsed host time, including any blocking or descheduling, not CPU execution time alone. A GPU kernel has its own start and end time on the correlated device timeline. The two intervals can overlap without having the same duration.
The same distinction applies to input transfers. images.to(device, non_blocking=True) can return on the host before the corresponding host-to-device copy finishes on the GPU, provided the source memory is suitable for asynchronous transfer.
2.2 NVTX gives the trace a vocabulary
Nsight Systems can record CUDA activity without any source changes, but raw kernel names are difficult to map back to the training loop. This excerpt shows the workload’s NVTX ranges around one training step; model, loss, optimizer, device, and batch-iterator setup are omitted:
with torch.cuda.nvtx.range("torch_step"):
  with torch.cuda.nvtx.range("data_load"):
    images, labels = next(batches)
    images = images.to(device, non_blocking=True,
               memory_format=torch.channels_last)
    labels = labels.to(device, non_blocking=True)

  with torch.cuda.nvtx.range("forward"):
    logits = big_model(images)
    loss = big_loss_fn(logits, labels)

  with torch.cuda.nvtx.range("zero_grad"):
    big_optimizer.zero_grad(set_to_none=True)
  with torch.cuda.nvtx.range("backward"):
    loss.backward()
  with torch.cuda.nvtx.range("optimizer_step"):
    big_optimizer.step()
The labels do not change the model. They make the timeline readable: a CUDA kernel can be inspected in the context of the phase that queued it.
2.3 What the capture contains
The original capture uses these options:
--trace=cuda,nvtx,osrt
--sample=none
--cpuctxsw=none
--capture-range=cudaProfilerApi
--capture-range-end=stop
cuda records CUDA API calls, kernels, and memory operations. nvtx records the ranges above. osrt adds operating-system runtime calls. Sampling and context-switch tracing are disabled, so this is a CUDA/NVTX timeline rather than a full CPU scheduling study.
--capture-range=cudaProfilerApi delays collection until the application’s profiler-start call. --capture-range-end=stop ends collection at the profiler-stop call while allowing the application to continue. The warm-up therefore runs outside the collected interval.
3. A minimal Nsight Systems example
3.1 The workload
The captured workload creates a ResNet-50 with a 101-class output layer and trains it on Food-101. The follow-up experiments in Section 8 parameterize the same workload. This setup excerpt shows the loader and model configuration:
food_train = datasets.Food101(
  root=DATA_DIR,
  split="train",
  transform=food_tf,
  download=False,
)
food_loader = DataLoader(
  food_train,
  batch_size=128,
  shuffle=True,
  num_workers=min(8, os.cpu_count()),
  pin_memory=True,
  persistent_workers=True,
)

big_model = models.resnet50(
  weights=None,
  num_classes=101,
).to(device, memory_format=torch.channels_last)
The loader decodes and augments images in worker processes. pin_memory=True places batches in page-locked host memory, allowing the asynchronous H2D copies in the training loop.
These are profiling excerpts, not a complete training script; imports, transforms, loss, optimizer, and helper definitions are omitted. Food-101 must already exist at DATA_DIR. Exact software versions and host configuration are not recorded here, so treat the timings as examples rather than reproduction targets.
3.2 Starting and stopping the capture
The workload runs three warm-up steps, then profiles eight steps and waits for their device work to finish. Warm-up reduces initialization effects but does not guarantee steady state:
train_step(3)
torch.cuda.synchronize()

torch.cuda.profiler.start()
train_step(8)
torch.cuda.synchronize()
torch.cuda.profiler.stop()
The torch.cuda.synchronize() before stop() is important for producing a complete report, but it also appears as a CUDA API wait. It must not be mistaken for eight per-step synchronizations.
There is another boundary hidden inside this example: the original train_step() calls iter(food_loader) each time. The measured call therefore resets the loader iterator after warm-up. Persistent workers avoid recreating worker processes, but do not eliminate iterator-reset and prefetch-replenishment effects. Section 8 compares this behavior with retaining the same iterator across warm-up and capture.
Reusing the iterator does not reuse the previous batch: each next(batches) advances to the next batch. After three warm-up batches, capture therefore continues with batch four of the same traversal. Calling iter(food_loader) again instead starts a new traversal, with a new shuffled ordering because this loader uses shuffle=True.
For an existing training script with these NVTX annotations and profiler start/stop calls, the command-line capture pattern is:
nsys profile \
  --trace=cuda,nvtx,osrt \
  --sample=none \
  --cpuctxsw=none \
  --capture-range=cudaProfilerApi \
  --capture-range-end=stop \
  --output=resnet50_food101 \
  python /path/to/your_training_script.py
Replace the script path with your complete workload to generate your own resnet50_food101.nsys-rep. The Nsight Systems CLI documentation covers these options and the export commands below; use the documentation matching your installed version.
3.3 Exporting the summaries
After capturing your own workload, export its report to SQLite and request four CSV summaries:
nsys export --type=sqlite --output=resnet50_food101.sqlite \
  resnet50_food101.nsys-rep

nsys stats \
  --report=nvtx_sum,cuda_gpu_kern_sum,cuda_gpu_mem_time_sum,cuda_api_sum \
  --format=csv --output=resnet50_food101 \
  resnet50_food101.sqlite
The SQLite export retains individual event timestamps for timeline analysis. nsys stats aggregates those records into one CSV per report, with names such as resnet50_food101_nvtx_sum.csv. These commands post-process your capture; they do not rerun training. Each summary answers a different question:
| Report | Question |
|---|---|
nvtx_sum | How long were the named logical ranges open? |
cuda_gpu_kern_sum | Which GPU kernel names consumed device time? |
cuda_gpu_mem_time_sum | How much device time was recorded for copies and memsets? |
cuda_api_sum | Which host-side CUDA calls took time or blocked? |
The tables below show the example’s summary results. Summaries discard event order, so Section 6 also includes individual event intervals and a timeline figure to explain overlap. The figures are custom visualizations, not automatic outputs of nsys stats.
4. Reading the NVTX summary
The first report covers eight torch_step ranges. The most important detail is not just the total, but the spread between the median and maximum. A large maximum means one or more steps stalled even when the average looks reasonable.
| Range | Calls | Total (ms) | Average (ms) | Median (ms) | Maximum (ms) |
|---|---|---|---|---|---|
torch_step | 8 | 751.230 | 93.904 | 28.526 | 568.712 |
data_load | 8 | 571.418 | 71.427 | 0.416 | 535.258 |
backward | 8 | 109.547 | 13.693 | 14.140 | 20.010 |
forward | 8 | 60.535 | 7.567 | 6.795 | 11.843 |
optimizer_step | 8 | 6.480 | 0.810 | 0.767 | 1.073 |
zero_grad | 8 | 2.529 | 0.316 | 0.303 | 0.415 |
The Nsight percentage column is a share of the sum of all reported NVTX ranges, so torch_step appears as 50.0% and data_load as 38.1%. These rows are nested ranges and are not mutually exclusive buckets.
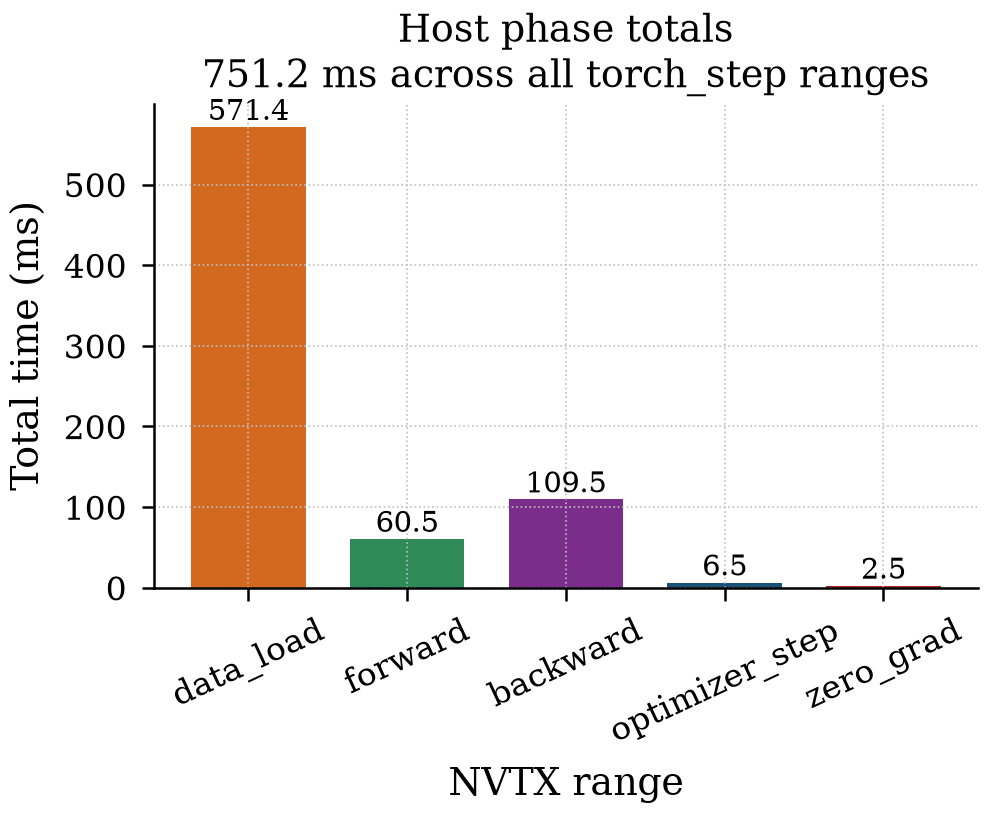
Figure 1. Total duration of each named phase range, excluding the enclosing torch_step, across the eight profiled steps. The bars show range duration, not exclusive GPU work.
The longest data_load interval accounts for 535.3 ms of its 571.4 ms total, leaving 36.2 ms across the other seven intervals. That makes input delivery the first investigation target without implying that all seven remaining steps were equally fast. The summary alone cannot tell us whether the GPU was idle during that host wait; the timeline can.
5. Three effects that shape the output
5.1 A range is not the same as GPU work
data_load is a host-side NVTX range. It includes waiting for the next batch and issuing the H2D transfers. Its duration says when the host entered and left the range; it does not say that the GPU was idle for the entire interval.
Likewise, forward covers the model call and loss calculation, including launch overhead and any host waits. To decide whether forward is the bottleneck, compare the range with the GPU kernels and with the neighboring backward work. The CPU may be launching the next forward while the GPU is still finishing the previous step.
5.2 The final drain completes outstanding training work
The CUDA API report contains one cudaDeviceSynchronize lasting 44.268 ms, or 38.6% of reported CUDA API time. This is the explicit synchronization after the eight profiled steps and before torch.cuda.profiler.stop().
| CUDA API call | Calls | Total (ms) | Share |
|---|---|---|---|
cudaDeviceSynchronize | 1 | 44.268 | 38.6% |
cuLaunchKernelEx | 1,240 | 19.518 | 17.0% |
cuMemsetD8Async | 432 | 16.378 | 14.3% |
cudaLaunchKernel | 1,656 | 16.044 | 14.0% |
cudaLaunchCooperativeKernel | 848 | 8.356 | 7.3% |
cudaMemsetAsync | 864 | 7.849 | 6.8% |
cudaMemcpyAsync | 24 | 0.689 | 0.6% |
This single wait completes outstanding work from the eight steps; it is not a 44 ms cost per step. Include the final synchronization when timing completed work, without adding overlapping host and kernel durations. Reading a CUDA tensor with .item() inside the loop can instead introduce waits during individual steps.
5.3 Kernel time is split across implementations
The GPU kernel report groups launches by demangled kernel name. The largest groups are:
| Kernel group | Calls | Total (ms) | Share |
|---|---|---|---|
| cuDNN batch-norm backward | 200 | 28.505 | 13.8% |
| cuDNN batch-norm forward | 200 | 23.480 | 11.4% |
PyTorch vectorized add | 256 | 18.642 | 9.0% |
| PyTorch vectorized binary elementwise | 384 | 16.051 | 7.8% |
| PyTorch vectorized clamp | 392 | 10.650 | 5.2% |
| cuDNN batch-norm backward variant | 224 | 10.409 | 5.0% |
| cuDNN batch-norm forward variant | 224 | 9.055 | 4.4% |
| CUTLASS tensorop weight-gradient | 144 | 7.230 | 3.5% |
| CUTLASS tensorop GEMM | 168 | 6.942 | 3.4% |
| NHWC max-pool backward | 8 | 5.705 | 2.8% |
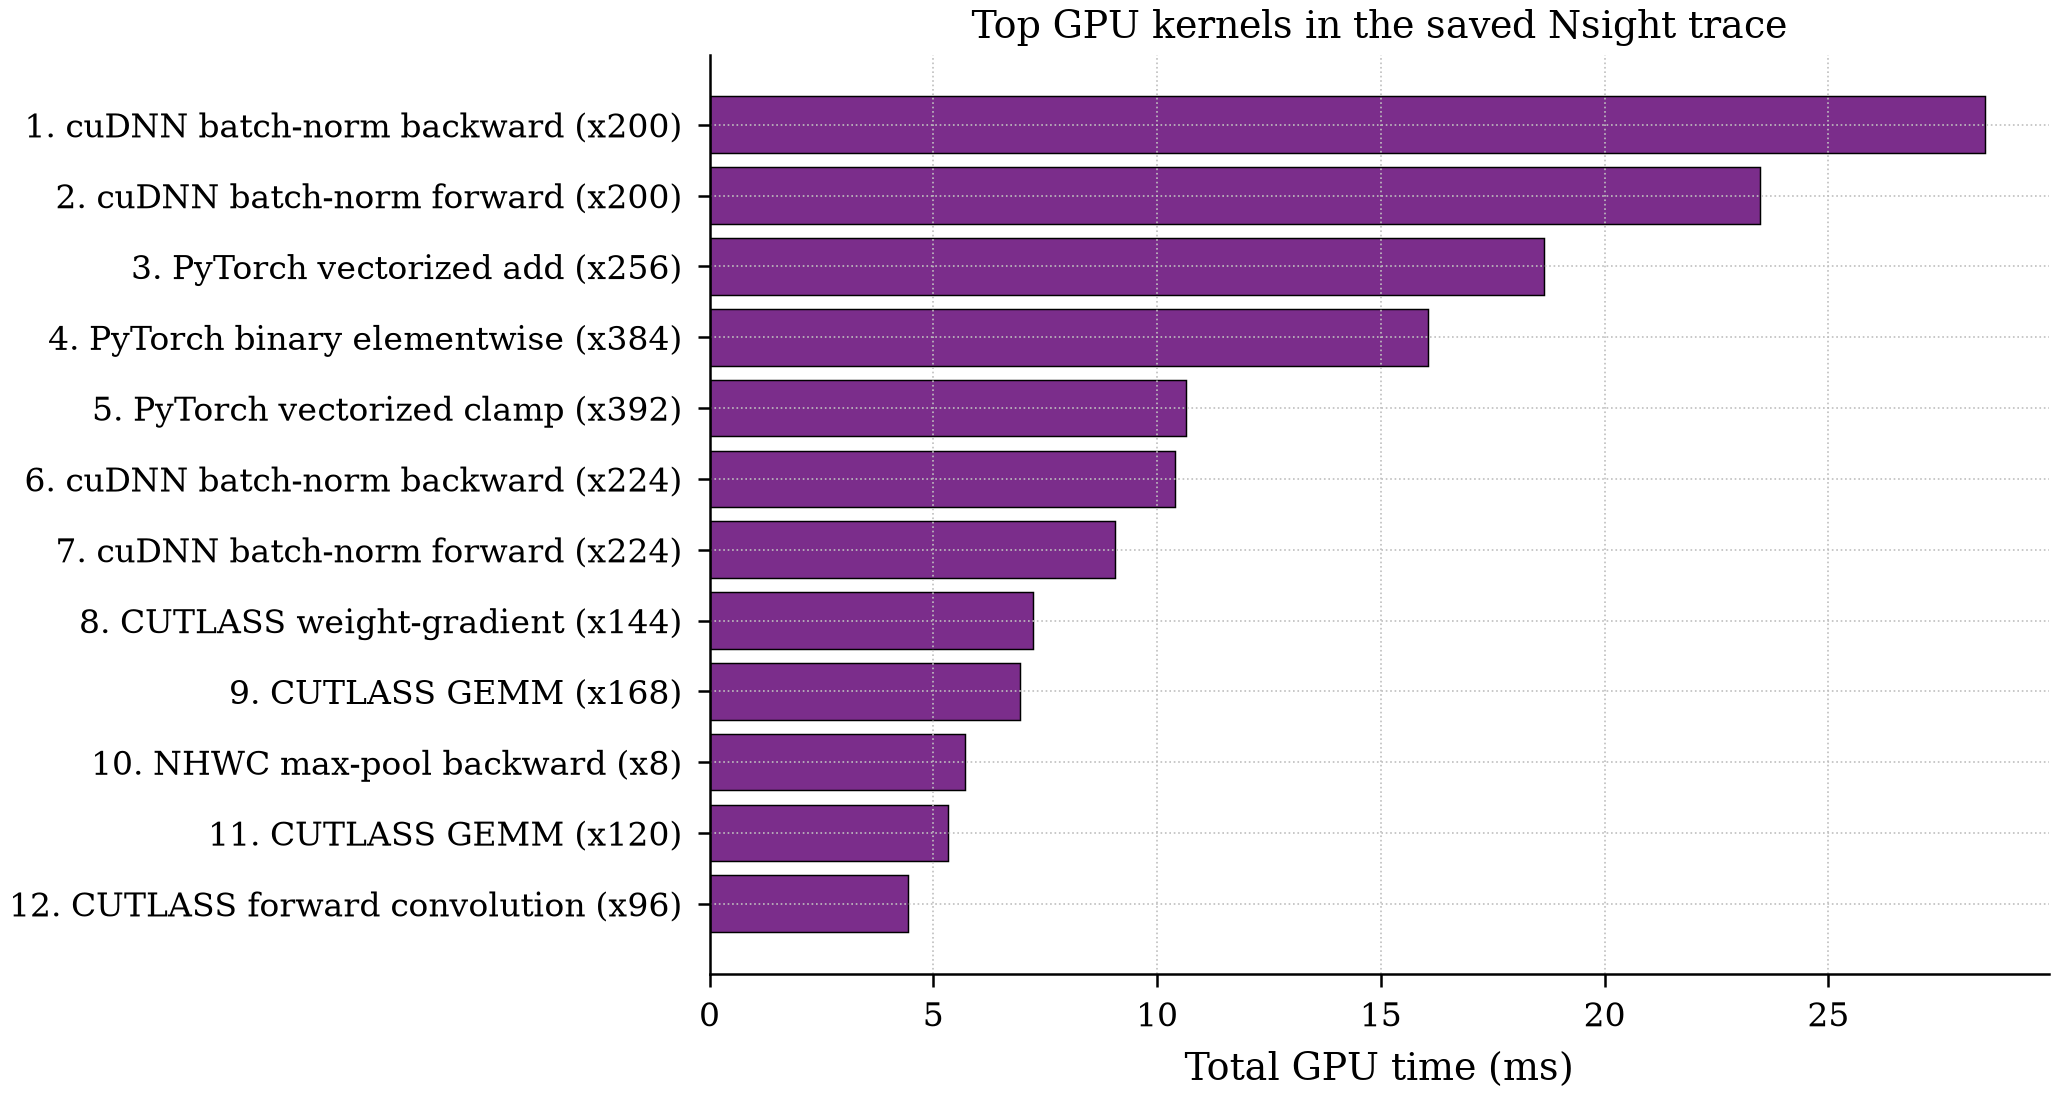
Figure 2. The twelve largest groups of identical demangled kernel names, with shortened operation labels and launch counts. Rank numbers distinguish separate implementations with the same short label; these bars are not aggregated operation-family totals.
The two leading batch-normalization groups total 51.985 ms. Elementwise work is spread across several generated kernels, so the largest individual bar is not automatically the best optimization target. Nsight Systems tells us which implementations ran; Nsight Compute is needed to explain occupancy, memory transactions, or warp stalls inside one of them.
6. Follow a batch through the GPU timeline
The timeline aligns records from the SQLite export:
- NVTX
torch_stepanddata_loadranges, which mark host-side steps and input delivery. - GPU kernel intervals, which show device execution.
- GPU memory-copy and memset intervals, displayed on separate lanes.
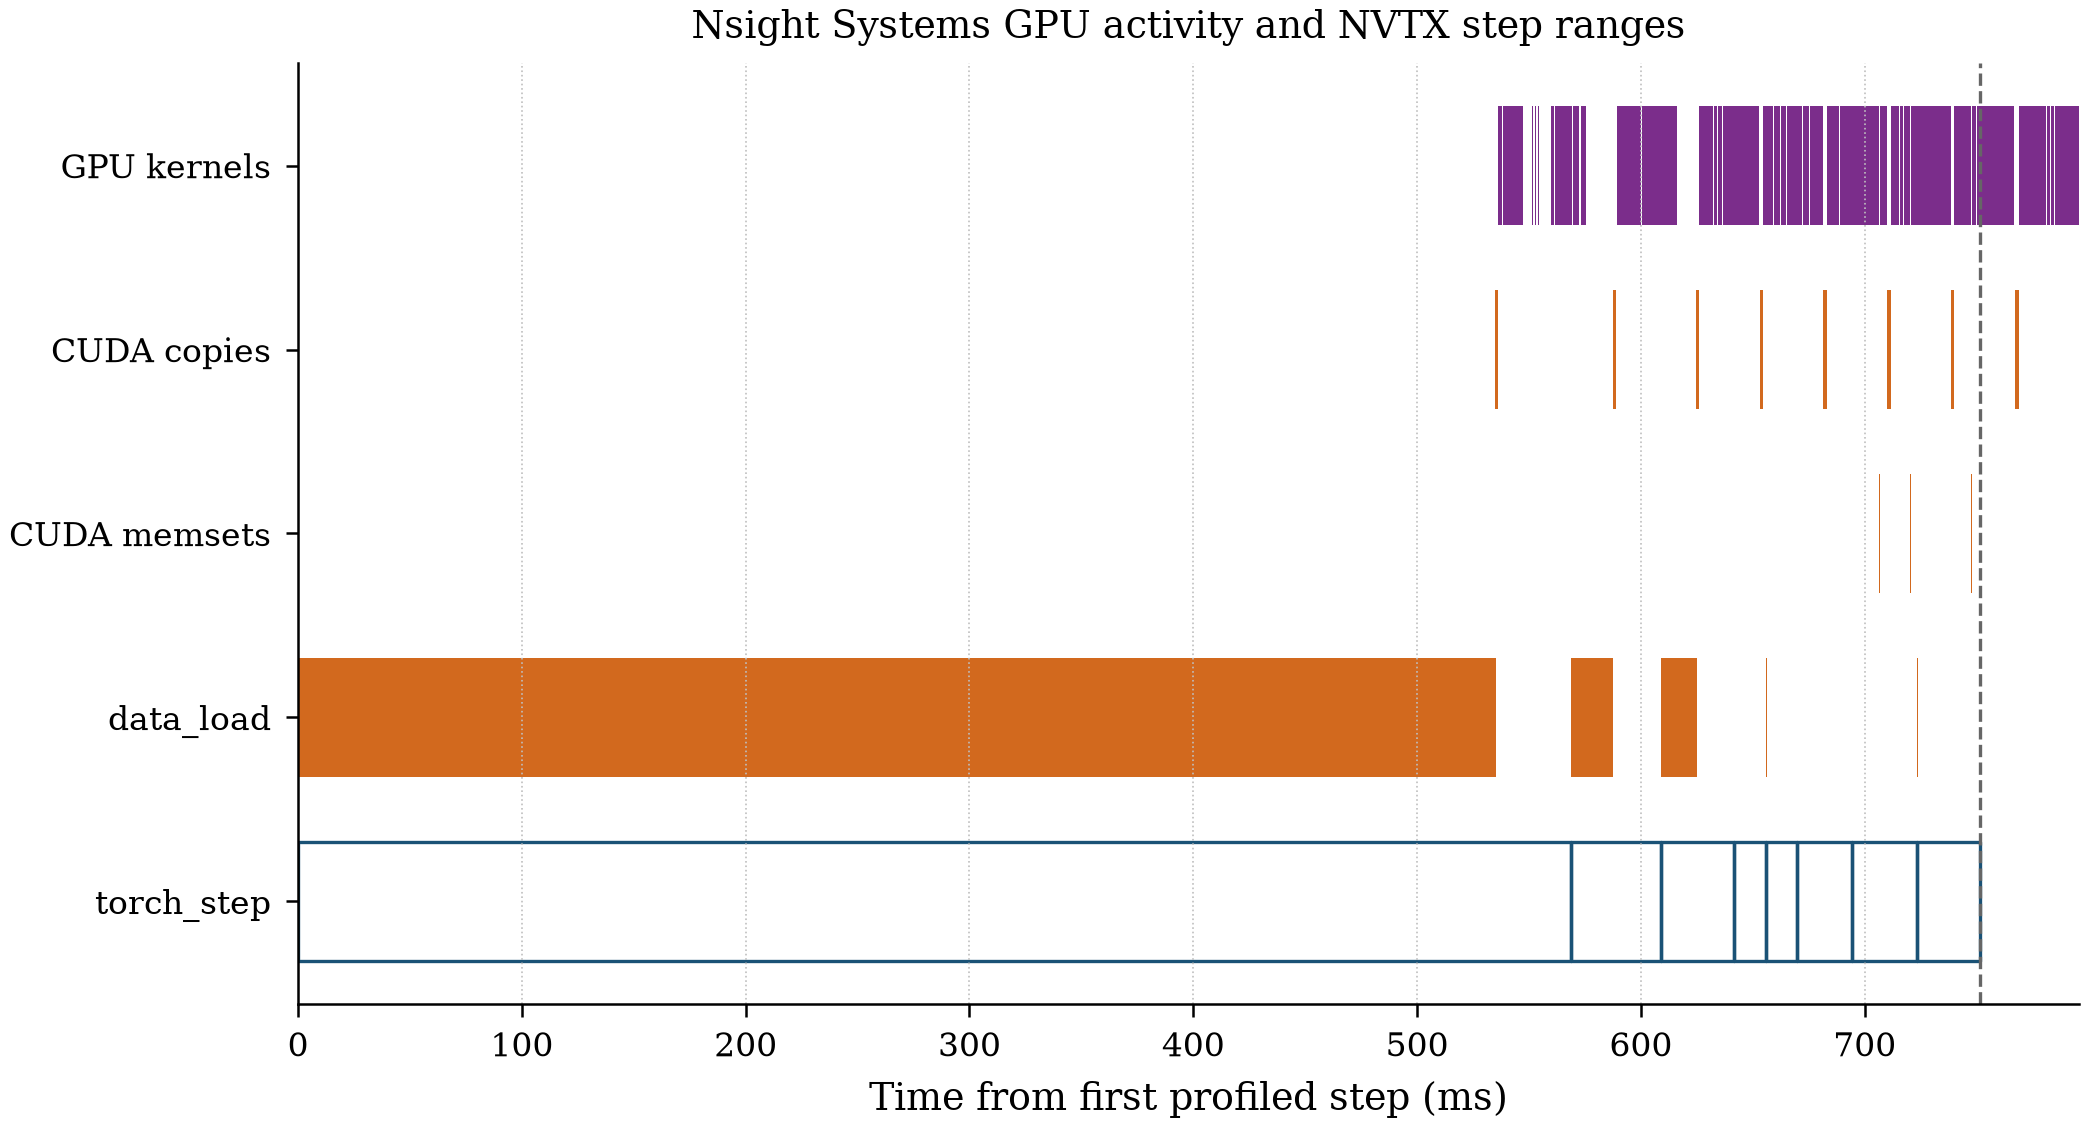
Figure 3. Recorded GPU activity and host ranges from the first profiled step through the last device operation. The dashed line marks the end of the last host step; GPU work to its right is completed during the final drain. This is an activity view, not the entire profiler-start-to-stop interval.
The first intervals make the host/device distinction concrete. Starts are relative to the first torch_step; durations are in milliseconds:
start_ms  duration_ms  activity
0.000     568.712      NVTX torch_step
0.009     535.258      NVTX data_load
534.757     1.459      H2D copy
536.223     0.054      GPU kernel
536.278     0.001      H2D copy
The host data_load range ends at ms. The first H2D copy starts at 534.757 ms and ends at ms. It begins before the host leaves data_load and continues for about 0.949 ms afterward. The range closing therefore does not mean the transfer is complete, and its 535.258 ms duration is not the copy’s 1.459 ms device duration.
The next kernel starts at 536.223 ms, after the copy ends. This establishes event order, not launch attribution. Attribution uses CUDA correlation IDs to link device work to a host call and its enclosing NVTX range; those links are not shown here.
Read the figure in this order:
- Find a long
torch_stepordata_loadrange. - Look above it for GPU kernels, memory copies, and memsets at the same time.
- If the GPU lane is still busy, the host delay is overlapped and may not reduce throughput.
- If all device lanes are empty, compare the gap with the host input range. Here the long initial
data_loadinterval overlaps a gap in recorded device activity, making input delivery the next investigation target. Section 8 separates batch waiting from transfer submission and compares input-pipeline settings.
In this original capture, the initial long input range coincides with roughly 535 ms without recorded device activity. Later host input waits can overlap GPU work. The figure establishes that distinction, but not the cause of the first wait.
The memory-operation summary provides the aggregate transfer view:
| GPU memory operation | Calls | Total (ms) | Share |
|---|---|---|---|
| Host-to-device copy | 16 | 13.207 | 87.3% |
| Device memset | 1,296 | 1.903 | 12.6% |
| Device-to-device copy | 8 | 0.013 | 0.1% |
The 16 H2D copies are consistent with image and label transfers across eight steps. The count is small, but their 13.207 ms is most of the GPU memory-operation time. That makes the H2D path worth following in the timeline, especially when data_load has a large maximum.
7. What we have learned so far
The timeline connects a large input wait with a gap in recorded device activity. The summaries also identify H2D copies as the dominant memory operation and batch normalization among the largest kernel groups. This tells us where to look, but not exactly why the input wait occurred.
This CUDA/NVTX capture does not include CPU scheduling samples or kernel-internal counters. Diagnosing a thread wait may need additional host tracing; understanding a kernel’s internal limits calls for Nsight Compute. For now, we can use the same timeline approach to see how input settings change the pattern.
8. See how input settings change the timeline
8.1 Separate waiting from submission
The following comparison covers eight configurations, each run twice in shuffled order with seeds 2026 and 2027. The baseline uses 64 steps, eight workers, prefetch factor two, pinned memory, and an iterator retained across warm-up and capture. The model, dataset, batch size, three-step warm-up, channels-last layout, SGD settings, and capture options remain the same.
These runs use another B300, CPU intra-op/OMP/MKL thread counts of one, and cuDNN benchmarking disabled. Compare settings within this group rather than against the earlier capture. Iterator and worker changes can also change batches and augmentation order.
Two nested ranges make the input phase more informative: batch_wait measures next(batches), while h2d_submit measures the host calls submitting transfers.
The first excerpt replaces data_load inside each training step:
with torch.cuda.nvtx.range("data_load"):
  with torch.cuda.nvtx.range("batch_wait"):
    images, labels = next(batches)
  with torch.cuda.nvtx.range("h2d_submit"):
    images = images.to(
      device, non_blocking=True,
      memory_format=torch.channels_last,
    )
    labels = labels.to(device, non_blocking=True)
A surrounding capture_window includes the measured steps and final drain. Here train_step() accepts an existing iterator, and config supplies the warm-up count, measured step count, batch size, and iterator-reuse setting:
batches = iter(food_loader)
train_step(config["warmup"], batches)
torch.cuda.synchronize()

torch.cuda.profiler.start()
started = time.perf_counter()
with torch.cuda.nvtx.range("capture_window"):
  if not config["reuse_iterator"]:
    with torch.cuda.nvtx.range("iterator_reset"):
      batches = iter(food_loader)
  train_step(config["steps"], batches)
  with torch.cuda.nvtx.range("capture_drain"):
    torch.cuda.synchronize()
elapsed = time.perf_counter() - started
torch.cuda.profiler.stop()

images_per_s = config["steps"] * config["batch_size"] / elapsed
Throughput counts completed images over host elapsed time through synchronization. The no-activity percentage is the fraction of capture_window left uncovered by any recorded kernel, copy, or memset. Device intervals are clipped to the window and overlapping intervals counted only once; this is not SM utilization.
All 16 completed runs passed step-count, copy-count, and capture-boundary checks. One timed-out four-worker attempt was excluded and retried successfully.
8.2 Results
Each pair below is repetition 1, repetition 2. Input statistics describe the full data_load range. All rows except the first two use 64 captured steps; each variant changes one setting from reuse_64.
| Configuration | Images/s (two runs) | No GPU activity (%) | Input median (ms) | Input max (ms) |
|---|---|---|---|---|
| reset_8 | 1035, 1154 | 77.4, 74.8 | 0.23, 0.32 | 671.0, 533.6 |
| reuse_8 | 4275, 4197 | 6.7, 8.3 | 1.30, 1.31 | 3.7, 4.6 |
| reuse_64 | 2570, 2518 | 44.0, 45.1 | 0.57, 0.47 | 327.6, 348.2 |
| pageable_64 | 2482, 2336 | 20.1, 22.3 | 27.47, 29.41 | 52.3, 107.2 |
| workers_4 | 1365, 1207 | 70.2, 73.8 | 0.25, 0.57 | 356.8, 560.1 |
| workers_12 | 4273, 3910 | 6.6, 14.3 | 0.31, 0.52 | 89.9, 147.5 |
| prefetch_1 | 2212, 2123 | 51.7, 53.7 | 0.70, 0.44 | 232.8, 405.0 |
| prefetch_4 | 3500, 3528 | 23.7, 23.3 | 0.24, 0.27 | 300.9, 276.3 |
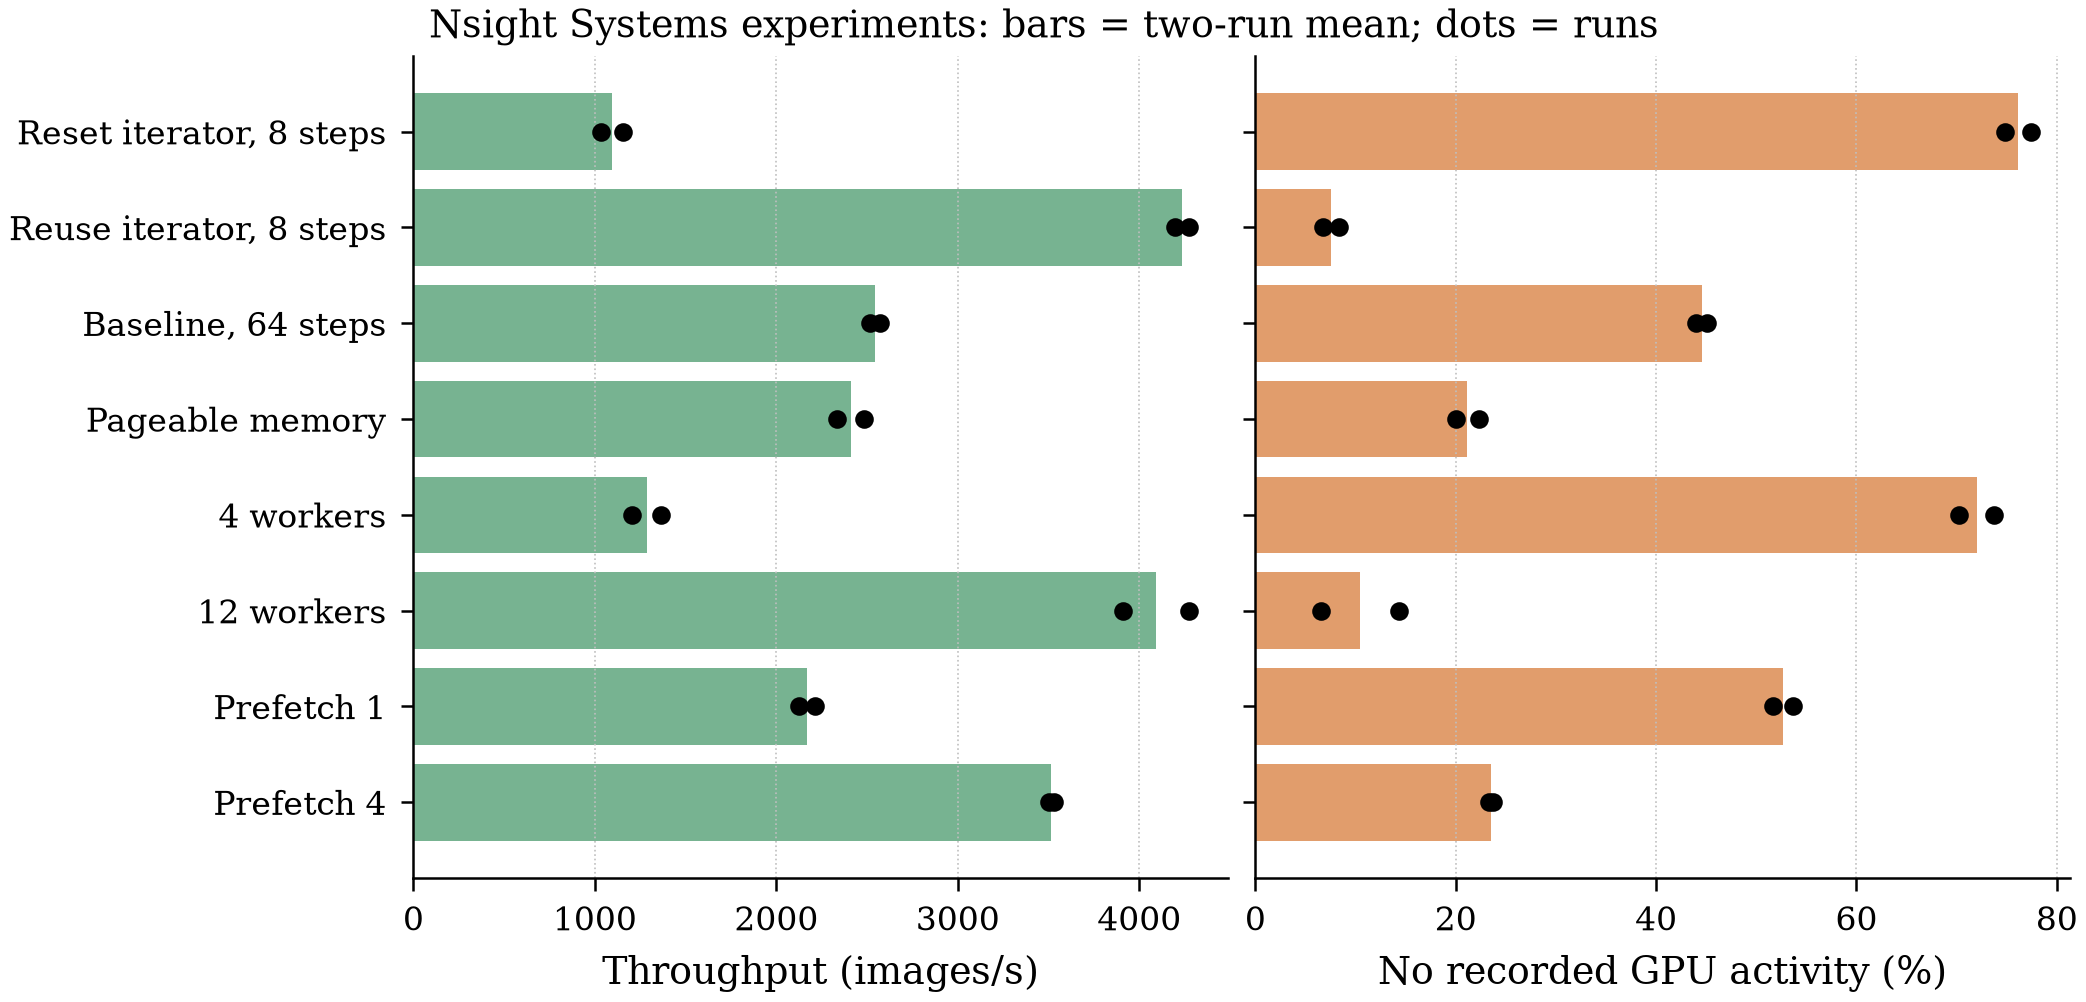
Figure 4. Synchronized throughput and the fraction of the capture window with no recorded GPU activity. Bars are two-run means; dots are individual runs, not confidence intervals.
8.3 What changed our interpretation?
Iterator reuse reduces the initial stall. The reset runs begin with 671.0 and 533.6 ms input ranges, compared with 3.7 and 4.6 ms when retaining the iterator. This points to iterator-boundary effects, although it does not identify the exact cause of the earlier 535 ms wait.
A short window can hide recurring waits. With iterator reuse, extending the window from eight to 64 steps lowers mean throughput from about 4,236 to 2,544 images/s. The long runs contain 1.61 and 1.57 seconds of batch waiting, versus 39.4 and 30.3 ms of host transfer submission. In the first long run, waits of 326.345 ms at step 54 and 319.022 ms at step 62 show that stalls occur well beyond startup. Prefetched batches may cushion the shorter window.
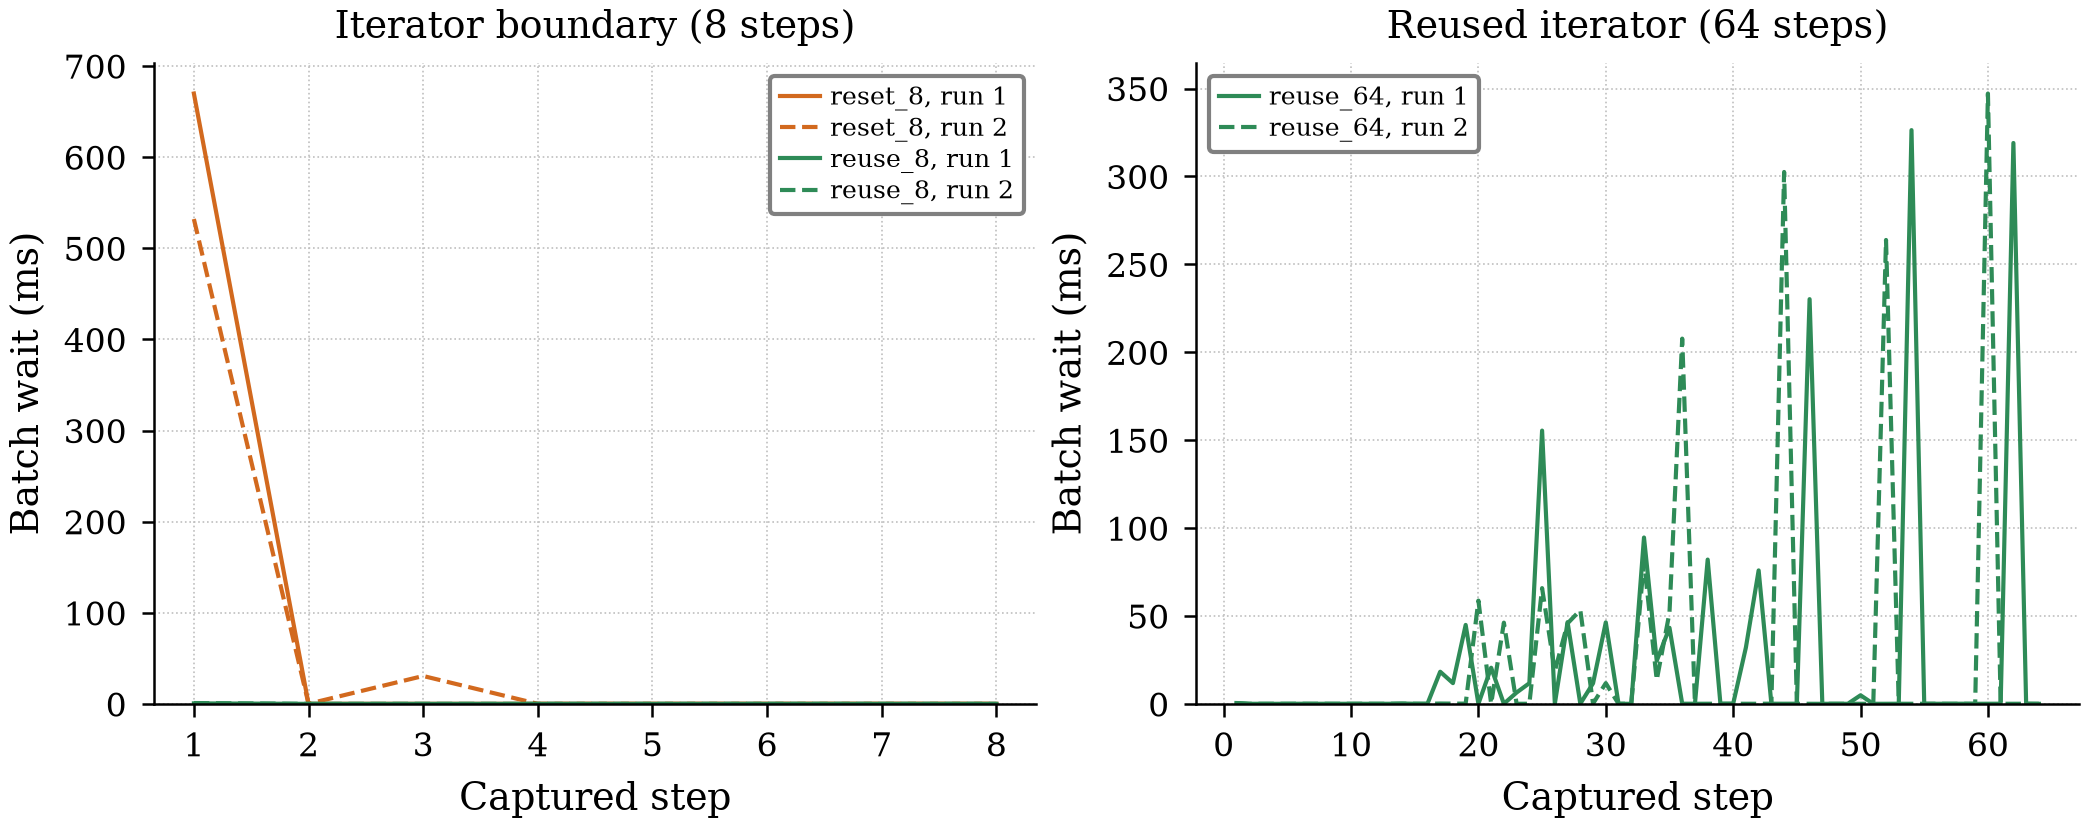
Figure 5. Time inside next(batches), excluding transfer submission. The left panel compares reset and reused iterators over eight steps. The right panel shows both 64-step baseline runs; panel scales differ.
Workers and prefetching affect delivery. Twelve workers and, separately, prefetch factor four improve throughput over the baseline in both runs. Four workers or prefetch factor one perform worse. This makes input production and buffering worth examining before individual kernels; the combined 12-worker/prefetch-four setting was not tested.
Pinning changes the transfer path. Without pinning, host H2D submission grows to 1.61 and 1.71 seconds across 64 steps, versus 39.4 and 30.3 ms in the pinned baseline. These are host submission times, not GPU-copy durations, so they do not tell us whether device transfers became longer or overlap changed.
9. Conclusion
Nsight Systems helps us connect what the host is doing with when work runs on the GPU. In this example, NVTX ranges made the training phases readable, while the device timeline showed which input waits overlapped GPU work and which coincided with gaps. Keeping host ranges, device execution, and synchronization separate is the main lesson: a long host wait need not leave the GPU idle, and a busier GPU timeline need not mean higher throughput.
The short captures and two-run comparisons illustrate how to read a profile, rather than establish an optimal input configuration. Results can vary with the workload and machine, and gaps here describe the captured work rather than all activity on the GPU. With that context, Nsight Systems is a useful starting point for deciding where to look more closely.